In my last SLOG Post, I will reflect upon my experience in the course how I've improved as a programmer since the beginning.
Overall, I enjoyed the course very much. I thought that the course material was both useful and interesting. My favourite part of the course was recursion, and in particular minimax. I really enjoyed Assignment 2 and 3 (Option A) because it felt like I was creating something that was somewhat complex,and could actually be used for something. The part I liked least was Assignment 1 and the whole section about inheritance and classes. While I understand how to implement classes and why they are important, I found all of the formatting and style guidelines to be pretty difficult to follow.
Throughout most of the year, I was able to keep on top of the material (the labs really helped with this). I did have some difficulty in the first few weeks. The learning environment was quite different from CSC108, where we would go through absolutely everything in lecture. In the first couple of labs, my quiz marks were pretty low because I was not properly prepared for them. However, pretty soon I decided that I should read over the lecture slides and start the lab assignments beforehand, and my marks improved.
There are two administrative aspects of this course that I really appreciated: Piazza and the marking scheme. Piazza was super helpful when I was working on the assignments. It allowed me to connect with other students and the instructors to find answers to my problems. Even just looking through the questions on piazza was a worthwhile exercise because it exposed me to different ways of approaching the problems that we were faced with. I also really liked the marking scheme because the marks were distributed across many tasks (the assignments, the labs, the tests, the exam, the SLOGs, etc.). As I'm a first year life science student, all of my non-CSC classes are really big, and the marking scheme for those classes is usually based on one or two midterms and a huge final exam. I prefer the CSC148 marking scheme because it takes the stress off of you, as you know that you won't be punished very hard for making mistakes on an assignment if most of your course work is done well.
After CSC148, I will further my programming knowledge at U of T by taking other computer science courses (like CSC165, CSC236, CSC263, and CSC265). My experience in CSC148 convinced me that computer science is something that I am interested in, and I am planning on doing a specialist in Bioinformatics so that I can learn about both computer science and biology.
Sunday, April 5, 2015

Friday, March 27, 2015
SLOG Post # 9 - Revisiting a previous SLOG
This week, we're supposed to write about a previous SLOG entry, and elaborate on it further. I've chosen to go back to Post #6 and talk a little more about Assignment 2.
In my original post, I expressed some concerns about the design of StrategyMinimax that my partner and I implemented for the project. In the post, I said that we had used "a recursive helper function, get_score, to find the score for every possible move at the current game state, and then use the Strategy class method suggest_move to (randomly) pick one of the moves that had the highest score" (if this isn't very clear, you could revisit Post #6 for a more thorough explanation). When I wrote that post, I wasn't sure if we had made the right decision about minimax, as our profs had described the recursive part of minimax as being able to store both the move and the score of the move, as a tuple. Even though we had tested it quite a bit, I didn't know if our implementation was correct or not.
Although we still haven't received the mark for Assignment 2 (because of the TA strike), last week I went to talk about it with Diane. She showed me the model code for the the minimax function, and it was as I had expected: the recursive helper function kept track of both the score and the move. Diane suggested that I test out our minimax function with the unittest that Danny created for the assignment. The unittest basically had a bunch of different scena//*rios that tested minimax's ability to return a correct move. Because there were so many cases, it was highly unlikely that an incorrect strategy (for example, the random move strategy) would pass. Our minimax function passed all parts of the test except for one section that involved setting up a game board. The reason our code failed here was because we had designed a different method of setting up a TippyGameState, and once I changed the unittest to be compatible with our setup, our minimax code passed all cases.
After this, I was quite confident that our minimax function was working properly. However, for Assignment 3 we decided to change our code to be more like the model version of minimax, since there was a major advantage to the way it was structured: it would be easier to implement certain features, like memoization, in a minimax strategy that kept track of both the move and the move's score within the recursive part of the code.
When I wrote Post #6, I thought that our minimax strategy implementation was inferior to the model version. However, I now believe that this is not the case: our minimax strategy was just as effective the model strategy. Furthermore, I believe that our strategy is easier to test. During development, we modified our code for the suggest_move method so that it returned a list of scores for each of the possible moves (as opposed to just returning the best move). The reason that we could do this was because, in our design, suggest_move creates two lists, a list of possible moves and a list of corresponding scores for those moves (obtained by get_score, the recursive helper function) (see more complete description in Post #6). This solves the major problem that the model minimax code has in testing: there is a chance that it will choose the correct move purely out of luck. Our program was better in a sense because it could show you a list of all the scores, making it easier to verify correctness.
This experience with Assignment 2 has allowed me to come to an important realization. At the beginning of the course, I always assumed that there was one "correct" way of doing things. In CSC108, we weren't given too much wiggle room on projects, and I think this may have given me the impression that every problem has one solution that is "better" than all of the others. When I look back at the minimax design in Assignment 2, and at the GameState class design in Assignment 1, I recognize there were many possible ways of approaching each problem, each with its own advantages and disadvantages. For every program, there isn't necessarily a design the is objectively better in all cases. One must weigh the costs and benefits of each design to determine which is the best for the specific situation. I'm confident that this knowledge will be useful to me in the future, as it will encourage me to pursue strange and creative solutions to the problems that I face.
When I wrote Post #6, I thought that our minimax strategy implementation was inferior to the model version. However, I now believe that this is not the case: our minimax strategy was just as effective the model strategy. Furthermore, I believe that our strategy is easier to test. During development, we modified our code for the suggest_move method so that it returned a list of scores for each of the possible moves (as opposed to just returning the best move). The reason that we could do this was because, in our design, suggest_move creates two lists, a list of possible moves and a list of corresponding scores for those moves (obtained by get_score, the recursive helper function) (see more complete description in Post #6). This solves the major problem that the model minimax code has in testing: there is a chance that it will choose the correct move purely out of luck. Our program was better in a sense because it could show you a list of all the scores, making it easier to verify correctness.
This experience with Assignment 2 has allowed me to come to an important realization. At the beginning of the course, I always assumed that there was one "correct" way of doing things. In CSC108, we weren't given too much wiggle room on projects, and I think this may have given me the impression that every problem has one solution that is "better" than all of the others. When I look back at the minimax design in Assignment 2, and at the GameState class design in Assignment 1, I recognize there were many possible ways of approaching each problem, each with its own advantages and disadvantages. For every program, there isn't necessarily a design the is objectively better in all cases. One must weigh the costs and benefits of each design to determine which is the best for the specific situation. I'm confident that this knowledge will be useful to me in the future, as it will encourage me to pursue strange and creative solutions to the problems that I face.
Sunday, March 22, 2015
SLOG Post # 8 - Linked Lists
This week we worked on linked lists. Linked lists are a type of data structure that is made up of a group of linked nodes that together form a sequence. They are really useful for storing things linearly, but cannot branch like trees can. Linked lists are created using a wrapper class. The nodes of the list are represented by the class LLNode, which stores the value of a node and the location of the next node (or None if there isn't one). The individual nodes are linked together by the class LList, which only contains the location of the first and last nodes and the size of the list.
I've noticed that many of the methods that we worked on for linked lists involve starting at the beginning and moving along the list until a certain condition is met (for example, a node with a specific value is reached). Often, it is useful to have a variable that keeps track of the node that was "visited" just before the current node, so that you can do things like delete the current node by connecting the previous node to one just after the current. As you can probably tell, linked lists are quite different from dictionaries or regular lists, in the sense that you can't use an index to refer to a specific position on the list by default: you would need to write a method that does that for you. Furthermore, dictionaries and lists are each represented by a single class (class dict and list, respectively): they lack the wrapper class structure that linked lists have.
I feel pretty comfortable with my understanding and implementation of linked lists. They're pretty straightforward, and most of the methods that we wrote for them were based on while loops, which were a main focus of CSC108. The most difficult part with linked lists, I find, is making sure that the methods you write will work for all possible scenarios. For example, if you have a function that inserts a node at a specific index in a list, it would need to behave differently at the beginning (where the is no previous node), the middle (where there is a previous node and a next node), and the end (where there is no next node). For functions that are more complicated, there can be even more distinct cases. I'm worried that I might forget some of the cases on the exam and produce code that is incomplete. This concern doesn't just apply to linked list questions: it's a valid concern for every test question, since you don't get the opportunity to run your code and see if it works. To try to minimize my chances of making an error, I will practice mentally tracing code that I've written (without using Python) so that I can easily check my answers during the test.
I've noticed that many of the methods that we worked on for linked lists involve starting at the beginning and moving along the list until a certain condition is met (for example, a node with a specific value is reached). Often, it is useful to have a variable that keeps track of the node that was "visited" just before the current node, so that you can do things like delete the current node by connecting the previous node to one just after the current. As you can probably tell, linked lists are quite different from dictionaries or regular lists, in the sense that you can't use an index to refer to a specific position on the list by default: you would need to write a method that does that for you. Furthermore, dictionaries and lists are each represented by a single class (class dict and list, respectively): they lack the wrapper class structure that linked lists have.
I feel pretty comfortable with my understanding and implementation of linked lists. They're pretty straightforward, and most of the methods that we wrote for them were based on while loops, which were a main focus of CSC108. The most difficult part with linked lists, I find, is making sure that the methods you write will work for all possible scenarios. For example, if you have a function that inserts a node at a specific index in a list, it would need to behave differently at the beginning (where the is no previous node), the middle (where there is a previous node and a next node), and the end (where there is no next node). For functions that are more complicated, there can be even more distinct cases. I'm worried that I might forget some of the cases on the exam and produce code that is incomplete. This concern doesn't just apply to linked list questions: it's a valid concern for every test question, since you don't get the opportunity to run your code and see if it works. To try to minimize my chances of making an error, I will practice mentally tracing code that I've written (without using Python) so that I can easily check my answers during the test.
Sunday, March 15, 2015
SLOG Post # 7 - Term Test 2 and Binary Search Trees
Term Test
This week's SLOG post will be about the second midterm test, which we wrote this week. The focus of this test was on recursive functions, trees, and linked lists. This was also our first test that, in my opinion, involved writing challenging code (our earlier test was really more about proper Python style and structure).
I think that I performed quite well on the test, although I am not certain as I haven't seen the marks yet. I employed the same sort of study methods as before. I went over the lecture slides, stopping whenever there was a practice question or function so that I could try it out myself. I also re-did all of the labs, making sure that I knew how to write the code for each function that we were assigned. I also put the code for some of the tricky functions on my "cheat sheet" for the test. This turned out to be a fantastic idea: some of the questions on the test were really similar to the ones that I had copied down.
Unlike the previous test, I didn't go through the course notes for the sections that were on the test. The main reason for this was that I was quite short on time: I also had to study for a physics midterm that was the night before. I don't think it significantly hindered my performance on the test, however. The course notes are really best for providing answers to tricky conceptual questions, and most of the questions on the test were practical questions that involved applying the concepts. Because these types of questions are so similar to the questions that we get on our labs, I was well prepared for them.
By now, I am pretty confident that my studying methods for CSC148 are quite effective. I will be using the same strategy for the final exam, and I'm optimistic that I will do quite well.
Binary Search Trees (BST's)
We also touched on BST's in class this week. BST's are trees that only contain numerical values* and an have an arity of two. The nodes in BST's are special: each node can have a left child (a node with a value less than the parent node's value) and a right child (a node with a value greater than the parent node's value). This creates two subtrees, a left subtree and a right subtree, in which all values are lower or higher (repectively) than the original parent node.
It's immediately apparent that BST's are quite powerful and useful as search tools. The left child-right child property makes it so that, when searching for a value in an ideal tree, very large portions of the tree can be skipped. To explain this I've included an optimal, or perfectly balanced, BST:

If you are looking for the value 111, you would only need to pass over 3 values (90, 150, and 95) before reaching 111.
However, there are some cases where a BST doesn't really help with your search efficiency, as is the case with this example:

Because each value is greater than the preceding value, the left child-right child property does not help since all the nodes are right children! this scenario is basically equivalent to a linked list: to get to 50, the last node, you'd need to pass through all of the other nodes to get to it.
I didn't have too much difficulty writing the binary search tree methods, which are usually recursive (like most of the regular tree methods). My TA had told me that when designing methods for BST's, it's best to consider the two simplest cases: a tree of height 1 (ie a node with no children) and a tree of height 2 (a node with a left child and a right child). If a method works for these two cases, it will (typically) work for all of them.
* Note: In our class, we only used BST's with numerical values. It is also possible to include other objects, as long as they also have an order (for example, letters).
This week's SLOG post will be about the second midterm test, which we wrote this week. The focus of this test was on recursive functions, trees, and linked lists. This was also our first test that, in my opinion, involved writing challenging code (our earlier test was really more about proper Python style and structure).
I think that I performed quite well on the test, although I am not certain as I haven't seen the marks yet. I employed the same sort of study methods as before. I went over the lecture slides, stopping whenever there was a practice question or function so that I could try it out myself. I also re-did all of the labs, making sure that I knew how to write the code for each function that we were assigned. I also put the code for some of the tricky functions on my "cheat sheet" for the test. This turned out to be a fantastic idea: some of the questions on the test were really similar to the ones that I had copied down.
Unlike the previous test, I didn't go through the course notes for the sections that were on the test. The main reason for this was that I was quite short on time: I also had to study for a physics midterm that was the night before. I don't think it significantly hindered my performance on the test, however. The course notes are really best for providing answers to tricky conceptual questions, and most of the questions on the test were practical questions that involved applying the concepts. Because these types of questions are so similar to the questions that we get on our labs, I was well prepared for them.
By now, I am pretty confident that my studying methods for CSC148 are quite effective. I will be using the same strategy for the final exam, and I'm optimistic that I will do quite well.
Binary Search Trees (BST's)
We also touched on BST's in class this week. BST's are trees that only contain numerical values* and an have an arity of two. The nodes in BST's are special: each node can have a left child (a node with a value less than the parent node's value) and a right child (a node with a value greater than the parent node's value). This creates two subtrees, a left subtree and a right subtree, in which all values are lower or higher (repectively) than the original parent node.
It's immediately apparent that BST's are quite powerful and useful as search tools. The left child-right child property makes it so that, when searching for a value in an ideal tree, very large portions of the tree can be skipped. To explain this I've included an optimal, or perfectly balanced, BST:
If you are looking for the value 111, you would only need to pass over 3 values (90, 150, and 95) before reaching 111.
However, there are some cases where a BST doesn't really help with your search efficiency, as is the case with this example:
Because each value is greater than the preceding value, the left child-right child property does not help since all the nodes are right children! this scenario is basically equivalent to a linked list: to get to 50, the last node, you'd need to pass through all of the other nodes to get to it.
I didn't have too much difficulty writing the binary search tree methods, which are usually recursive (like most of the regular tree methods). My TA had told me that when designing methods for BST's, it's best to consider the two simplest cases: a tree of height 1 (ie a node with no children) and a tree of height 2 (a node with a left child and a right child). If a method works for these two cases, it will (typically) work for all of them.
* Note: In our class, we only used BST's with numerical values. It is also possible to include other objects, as long as they also have an order (for example, letters).
Sunday, March 8, 2015
SLOG Post #6 - Assignment 2
For this week's SLOG post, I'm going to reflect on Assignment 2. Overall, I think this project went quite well. I liked it a lot more than the first assignment because I found that the tasks were a lot more clearly defined, which made it less stressful on our end. The most difficult part for me was writing the minimax strategy. I spent a long time reading the instructions sheet and trying to wrap my head around it. I found that drawing out Trees was really helpful during the design process. It made it really easy for me to trace the function and understand what it needed to do.
Minimax
Early on, I made an important design decision for the implementation of minimax: I would use a recursive helper function, get_score, to find the score for every possible move at the current game state, and then use the Strategy class method suggest_move to (randomly) pick one of the moves that had the highest score. This allowed me to create a recursive function that only needed to keep track of score, but not move. I've included the Tree from the assignment sheet as an example:

Imagine that it is player A's turn (the computer) in a game of Subtract Square, the current number is 6. Once the computer asks for a move suggestion using minimax, the StrategyMinimax method suggest_move calls get_score on the game states that can be reached with the two possible valid moves that can be made at that point (subtract 1 and subtract 4). get_score would recurse down these two "subtrees" to find the score for player A at both of these game states. In this case, subtracting 4 would lead to a winning game state where A has a score of +1 (B:2), and subtracting 1 would also lead to a winning game state (B:5, +1 for A). Upon knowing the scores, suggest_move randomly returns one of the moves that leads to a game state with the highest score (in this case, they both have the same score, so it doesn't matter which is returned). suggest_move keeps track of which score is associated with each move by keeping two parallel lists, one with game states that can be reached from the current game state, and one with scores (produced by get_score) that are in the same order as the game states.
So that's how my minimax strategy worked. I read the post on Biron's SLOG (http://grandslog148.blogspot.ca/, Week 7 and Assignment 2), and I sympathize with his struggle to design minimax. This function was quite difficult for me, and it took much longer to figure out than anything I've had to do in other computer science projects.
Based on what the other students have done, and on what our profs have told us, I don't think my implementation is quite the same as the expected or "correct" implementation. However, I'm pretty confident that it works, and I have thoroughly tested it. I fear that I might lose some credit because, technically, it does not work exactly as their description of minimax does: the recursive part of the strategy does not keep track of the moves as it recurses: it only carries the score.
Python Style Checker
I was having some issues with the python style checker, pep8. I noticed that it would give me an error for having lines that were greater than 79 characters for some of my docstring examples that involved dictionaries. However, I couldn't think of a way to fix it, since condensing the dictionaries (ie fitting them on multiple lines) would cause the doctest to fail, and that was also something that I wanted to avoid. I will be sure to find a solution to this problem before I hand in Assignment 3.
Minimax
Early on, I made an important design decision for the implementation of minimax: I would use a recursive helper function, get_score, to find the score for every possible move at the current game state, and then use the Strategy class method suggest_move to (randomly) pick one of the moves that had the highest score. This allowed me to create a recursive function that only needed to keep track of score, but not move. I've included the Tree from the assignment sheet as an example:
Imagine that it is player A's turn (the computer) in a game of Subtract Square, the current number is 6. Once the computer asks for a move suggestion using minimax, the StrategyMinimax method suggest_move calls get_score on the game states that can be reached with the two possible valid moves that can be made at that point (subtract 1 and subtract 4). get_score would recurse down these two "subtrees" to find the score for player A at both of these game states. In this case, subtracting 4 would lead to a winning game state where A has a score of +1 (B:2), and subtracting 1 would also lead to a winning game state (B:5, +1 for A). Upon knowing the scores, suggest_move randomly returns one of the moves that leads to a game state with the highest score (in this case, they both have the same score, so it doesn't matter which is returned). suggest_move keeps track of which score is associated with each move by keeping two parallel lists, one with game states that can be reached from the current game state, and one with scores (produced by get_score) that are in the same order as the game states.
So that's how my minimax strategy worked. I read the post on Biron's SLOG (http://grandslog148.blogspot.ca/, Week 7 and Assignment 2), and I sympathize with his struggle to design minimax. This function was quite difficult for me, and it took much longer to figure out than anything I've had to do in other computer science projects.
Python Style Checker
I was having some issues with the python style checker, pep8. I noticed that it would give me an error for having lines that were greater than 79 characters for some of my docstring examples that involved dictionaries. However, I couldn't think of a way to fix it, since condensing the dictionaries (ie fitting them on multiple lines) would cause the doctest to fail, and that was also something that I wanted to avoid. I will be sure to find a solution to this problem before I hand in Assignment 3.
Sunday, March 1, 2015
SLOG Post #5 - Summary of Recursion
What is Recursion?
According to "How to Think Like a Computer Scientist", recursive code is code that is defined in terms of itself. In practice, this means a function that calls itself within its own function body. While this style of programming may not be easy to grasp initially, it has many advantages and unique characteristics that make it a good skill to have.
Recursion is useful because you can write code that can solve complicated problems
as long as it works in a few key, simple scenarios. Essentially, you can create a simple function that repeatedly calls itself to break down the task into a series of short identical steps, without having to know or keep track of how many times the function has been called.
Examples of Recursion
A good example of the applications of recursion are fractals, which are shapes that can be created using recursive instructions. The Koch fractal is a particular fractal that has the appearance of "budding" triangles. Koch fractals have different orders: zeroth order is just a straight line; first order is like zeroth order with a triangular peak in the middle; second order is like the first order, except each line segment of the first has a triangular peak in the middle; and so on and so forth. Here is an image of the "evolution" of a Koch fractal (note: in this diagram, iteration has the same meaning as order):

Sometimes fractals can get a bit out of hand. Here is an image of a Koch "snowflake" fractal:
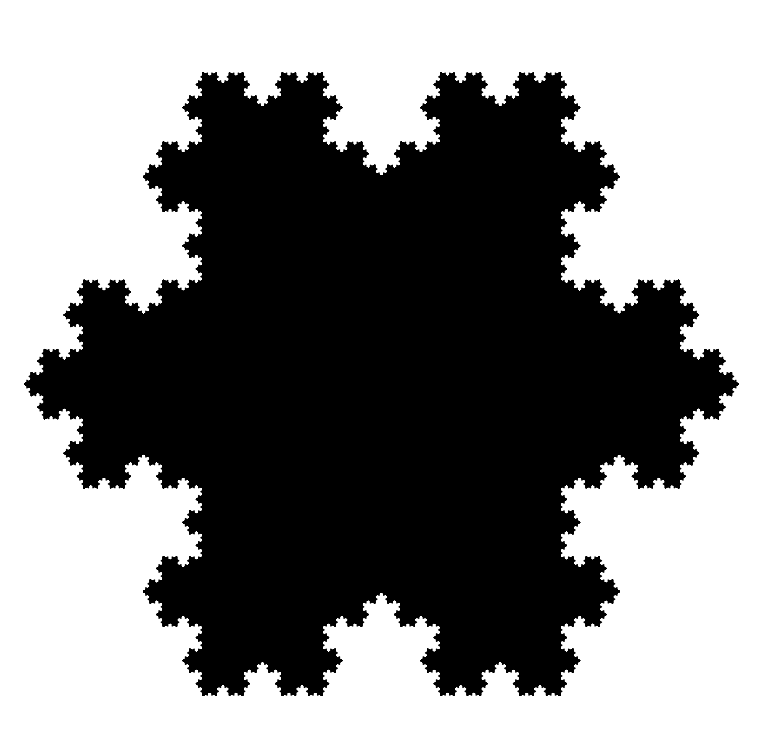
The amazing part about Koch fractals is that they only need a few lines of code to generate! It's almost unbelievable that such complicated shapes could be generated with such simple, repetitive instructions. This is the true beauty of recursion. Here's the code for the linear Koch fractal:
(from "How to Think Like a Computer Scientist", http://openbookproject.net/thinkcs/python/english3e/recursion.html)
Recursion is also particularly useful for sifting through complicated arrays, such as arbitraily nested lists, and for working with recursive series, such as the Fibonnacci series. In fact, you can apply recursion to a great deal of problems, as long as you make sure that you understand how it works for each problem (ie. you should be able to trace it!)
Tracing Recursive Functions
In the CSC148 labs periods, we have been developing two main recursion-related skills: tracing recursive code, and writing code for simple recursive functions. I quite enjoyed learning about tracing. In CSC108, I would often take shortcuts in practice problems that required us to trace the entire function call simply because I was being lazy, but for recursive function tracing, I was actually encouraged to do so! When we traced in our labs, we learned that it's not necessary to show steps that have already been demonstrated to work in similar scenarios. For example, one of the functions that we traced was a function that finds the maximum degree of nesting in a list. Once we had traced the function call on a list of first degree nesting, we didn't have to trace that process again when the function was called on a list of second degree nesting. We traced this way to reinforce the idea that you can trust a function to work in complex tasks if those tasks are a composition of many smaller, simpler tasks that you know the function can work with.
Writing Recursive Code
After tracing, we moved on to writing recursive code. I'll admit that initially, writing our own recursive functions was a little difficult. After looking at many examples and trying out a few questions, I soon discovered that there are some things that you should avoid when writing recursive functions. For example, you shouldn't accumulate data in a variable within the function body (ie. a counter) because the information stored in that variable is lost every time you call the function! Instead, you can put that variable as one of the arguments of the function, so that it isn't lost. I also learned that it's generally a good idea to start off by defining your base case and then figuring out how to solve the simplest example that isn't your base case. For example, if you are writing a recursive function for a Tree, your base case will probably be a Tree of depth 1, and the next simplest case would be a Tree of depth 2. If your code works for a Tree of depth 2, it can probably work for Trees of arbitrarily large depths. In this way, writing recursive functions is similar to writing test cases: you need to choose the cases that matter, all others are superfluous.
The Verdict
Recursion has been my favourite topic in CSC148 so far this year. I really like how recursive functions can be so concise, and I think that they're going to be a very useful addition to my toolbox of programming skills.
According to "How to Think Like a Computer Scientist", recursive code is code that is defined in terms of itself. In practice, this means a function that calls itself within its own function body. While this style of programming may not be easy to grasp initially, it has many advantages and unique characteristics that make it a good skill to have.
Recursion is useful because you can write code that can solve complicated problems
as long as it works in a few key, simple scenarios. Essentially, you can create a simple function that repeatedly calls itself to break down the task into a series of short identical steps, without having to know or keep track of how many times the function has been called.
Examples of Recursion
A good example of the applications of recursion are fractals, which are shapes that can be created using recursive instructions. The Koch fractal is a particular fractal that has the appearance of "budding" triangles. Koch fractals have different orders: zeroth order is just a straight line; first order is like zeroth order with a triangular peak in the middle; second order is like the first order, except each line segment of the first has a triangular peak in the middle; and so on and so forth. Here is an image of the "evolution" of a Koch fractal (note: in this diagram, iteration has the same meaning as order):
Sometimes fractals can get a bit out of hand. Here is an image of a Koch "snowflake" fractal:
The amazing part about Koch fractals is that they only need a few lines of code to generate! It's almost unbelievable that such complicated shapes could be generated with such simple, repetitive instructions. This is the true beauty of recursion. Here's the code for the linear Koch fractal:
(from "How to Think Like a Computer Scientist", http://openbookproject.net/thinkcs/python/english3e/recursion.html)
Recursion is also particularly useful for sifting through complicated arrays, such as arbitraily nested lists, and for working with recursive series, such as the Fibonnacci series. In fact, you can apply recursion to a great deal of problems, as long as you make sure that you understand how it works for each problem (ie. you should be able to trace it!)
Tracing Recursive Functions
In the CSC148 labs periods, we have been developing two main recursion-related skills: tracing recursive code, and writing code for simple recursive functions. I quite enjoyed learning about tracing. In CSC108, I would often take shortcuts in practice problems that required us to trace the entire function call simply because I was being lazy, but for recursive function tracing, I was actually encouraged to do so! When we traced in our labs, we learned that it's not necessary to show steps that have already been demonstrated to work in similar scenarios. For example, one of the functions that we traced was a function that finds the maximum degree of nesting in a list. Once we had traced the function call on a list of first degree nesting, we didn't have to trace that process again when the function was called on a list of second degree nesting. We traced this way to reinforce the idea that you can trust a function to work in complex tasks if those tasks are a composition of many smaller, simpler tasks that you know the function can work with.
Writing Recursive Code
After tracing, we moved on to writing recursive code. I'll admit that initially, writing our own recursive functions was a little difficult. After looking at many examples and trying out a few questions, I soon discovered that there are some things that you should avoid when writing recursive functions. For example, you shouldn't accumulate data in a variable within the function body (ie. a counter) because the information stored in that variable is lost every time you call the function! Instead, you can put that variable as one of the arguments of the function, so that it isn't lost. I also learned that it's generally a good idea to start off by defining your base case and then figuring out how to solve the simplest example that isn't your base case. For example, if you are writing a recursive function for a Tree, your base case will probably be a Tree of depth 1, and the next simplest case would be a Tree of depth 2. If your code works for a Tree of depth 2, it can probably work for Trees of arbitrarily large depths. In this way, writing recursive functions is similar to writing test cases: you need to choose the cases that matter, all others are superfluous.
The Verdict
Recursion has been my favourite topic in CSC148 so far this year. I really like how recursive functions can be so concise, and I think that they're going to be a very useful addition to my toolbox of programming skills.
Saturday, February 14, 2015
SLOG Post #4 - Summary of Object-Oriented Programming
This week I will be giving my thoughts on Object-Oriented Programming (OOP). OOP has been the focus of csc148 up until this point, and one of the major factors that distinguishes it from its prerequisite, csc108. While it is true that we learned how to define classes and class methods, we never really learned what they were used for. In fact, I remember thinking that they were pretty useless, just a laborious way of storing information that could be stored in other ways (like a dictionary). However, I know now that this is far from the truth: OOP is used almost everywhere, and is one of the most important developments in programming as a whole. Many of the most common languages, like Java, C++, C#, Perl, and of course Python, support a an object-oriented paradigm. It is a necessary tool for any programmer to have.
What OOP is:
OOP is a form of programming that centres on objects, data structures that contain attributes (the data that is being stored) and methods (functions that can operate on the object and access/change the attributes). In our class, we used Python to define new classes of object that represent different kinds of information, like the location of a point on a Cartesian plane or a shopping list with various items. Python already some with a bunch of pre-made classes (like str, int, list, etc), but making your own classes can be much easier than working with the ones that you're given in certain situations.
What inheritance is:
One of the biggest (and in my opinion, coolest) concepts in OOP is class inheritance. This is the idea that you can define a general class that contains a group of more specific (but related) subclasses. The general class never even needs to be used! It's just there to store attributes and methods that are common to the subclasses. For example, you could have a general class "Animal" and multiple specific subclasses like "Dog", "Cat", and "Zebra". In your general class, you'd have methods that work for all animals (like find_mate() or eat()), and in the specific classes you'd have the more specific methods (like fetch() for class Dog or purr() for class Cat). You can also put methods in you general class that are common to all subclasses but implemented differently in each one: all you need to do is define the function and raise a NotImplementedError exception. We put this property of OOP to good use in Assignment 1 (see SLOG post 3).
Challenges:
Overall I didn't find OOP (and inheritance) too diffuclt to grasp. Indeed, the hardest part was getting used to the formatting conventions for designing classes, in particular the docstrings for the different methods. However, I do occasionally find it difficult to understand exactly what kinds of methods a class would need given a written description. Luckily, in the computer labs we had many chances to practice doing this sort of excercise, and I think that I got much better at doing it (my term test mark was much higher than my quiz marks for labs 1 and 2).
Other SLOGs:
I really enjoyed reading the post about OOP on myslogisbest.blogspot.ca (post on Feb. 20). I found the slogger's views to be generally in line with my impressions of both the course and the object-oriented programming style. I also liked the diagram of object-oriented programming on jerrycsc148slog.blogspot.ca (post on Feb. 14), it's cute and it definitely illustrates the idea well.
What OOP is:
OOP is a form of programming that centres on objects, data structures that contain attributes (the data that is being stored) and methods (functions that can operate on the object and access/change the attributes). In our class, we used Python to define new classes of object that represent different kinds of information, like the location of a point on a Cartesian plane or a shopping list with various items. Python already some with a bunch of pre-made classes (like str, int, list, etc), but making your own classes can be much easier than working with the ones that you're given in certain situations.
What inheritance is:
One of the biggest (and in my opinion, coolest) concepts in OOP is class inheritance. This is the idea that you can define a general class that contains a group of more specific (but related) subclasses. The general class never even needs to be used! It's just there to store attributes and methods that are common to the subclasses. For example, you could have a general class "Animal" and multiple specific subclasses like "Dog", "Cat", and "Zebra". In your general class, you'd have methods that work for all animals (like find_mate() or eat()), and in the specific classes you'd have the more specific methods (like fetch() for class Dog or purr() for class Cat). You can also put methods in you general class that are common to all subclasses but implemented differently in each one: all you need to do is define the function and raise a NotImplementedError exception. We put this property of OOP to good use in Assignment 1 (see SLOG post 3).
Challenges:
Overall I didn't find OOP (and inheritance) too diffuclt to grasp. Indeed, the hardest part was getting used to the formatting conventions for designing classes, in particular the docstrings for the different methods. However, I do occasionally find it difficult to understand exactly what kinds of methods a class would need given a written description. Luckily, in the computer labs we had many chances to practice doing this sort of excercise, and I think that I got much better at doing it (my term test mark was much higher than my quiz marks for labs 1 and 2).
Other SLOGs:
I really enjoyed reading the post about OOP on myslogisbest.blogspot.ca (post on Feb. 20). I found the slogger's views to be generally in line with my impressions of both the course and the object-oriented programming style. I also liked the diagram of object-oriented programming on jerrycsc148slog.blogspot.ca (post on Feb. 14), it's cute and it definitely illustrates the idea well.
Subscribe to:
Posts (Atom)